6 - Language
本页目录
Natural Language Processing (NLP)
Language
- Syntax - structure
- Semantics - meaning
Grammar
Formal grammar: a system of rules for generating sentences in a language.
- Context-Free grammar
- e.g. She saw the city. - NVDN
- N : Noun
- V : Verb
- D : Determiner
- NP (Noun Phrase : N | D NP), VP (Verb Phrase : V | V NP), S (Sentence)
- S -> NP VP
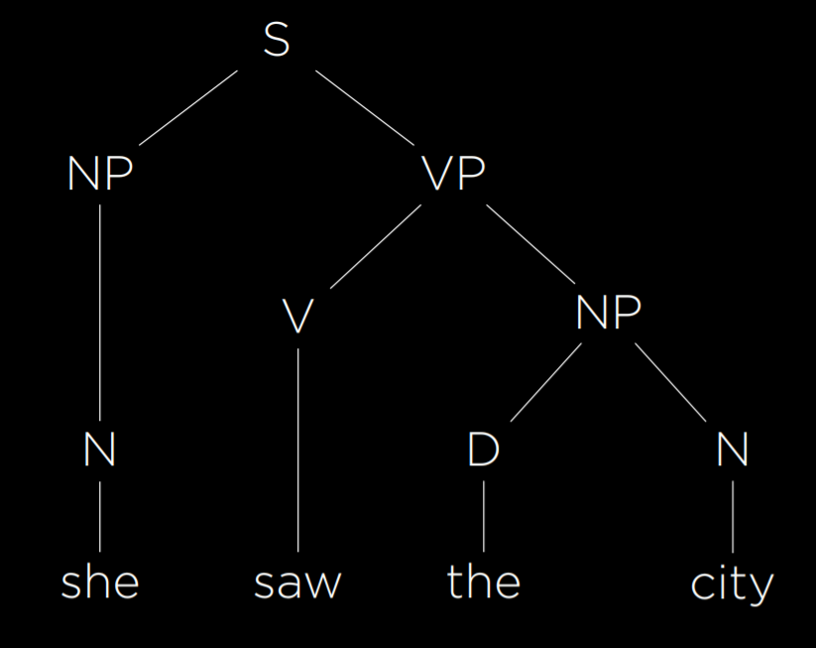
- Others: AP (Adjective Phrase), PP (Propositional Phrase) …
Python lib nltk
N-grams
N-grams: use n continuous grams(here a word) to understand the language.
Tokenization: splitting a sequence of characters into pieces (tokens)
We can use n-grams with Markov Chain to understand natural language and generate some sentence.
Text Classification
Bag-of-words Model: represents text as an unordered collection of words.
To do text classification, we can use Naive Bayes:
P(a|b)= \frac{P(a)P(b|a)}{P(b)}
E.g. we have to classes, positive and negative. We first separate the sentence into words w_{1},w_{2},\dots,w_{n}. And we naively assume all the words are independent.
Then the probability that the sentence is positive is:
P(\text{positive} |w_{1},w_{2},\dots,w_{n})= \frac{P(\text{positive})P(w_{1}|\text{posivite})\dots P(w_{n}|\text{positive})}{P(w_{1})\dots P(w_{n})}
And the right hand side can be calculate easily.
To avoid the case that a word never appear in our training data (and make the probability 0), we use:
- Laplace smoothing: add 1 to each value in our distribution.
Word Representation
Turn words into numbers.
- One-hot representation: a word is a vector with a single 1 and with others 0. (cannot represent similar words)
- Distributed representation: meaning distributed across multiple values.
- Similar meaning = similar context
word2vecmodel
Attention
Attention score: how important the word is. (a weight)
Transformers
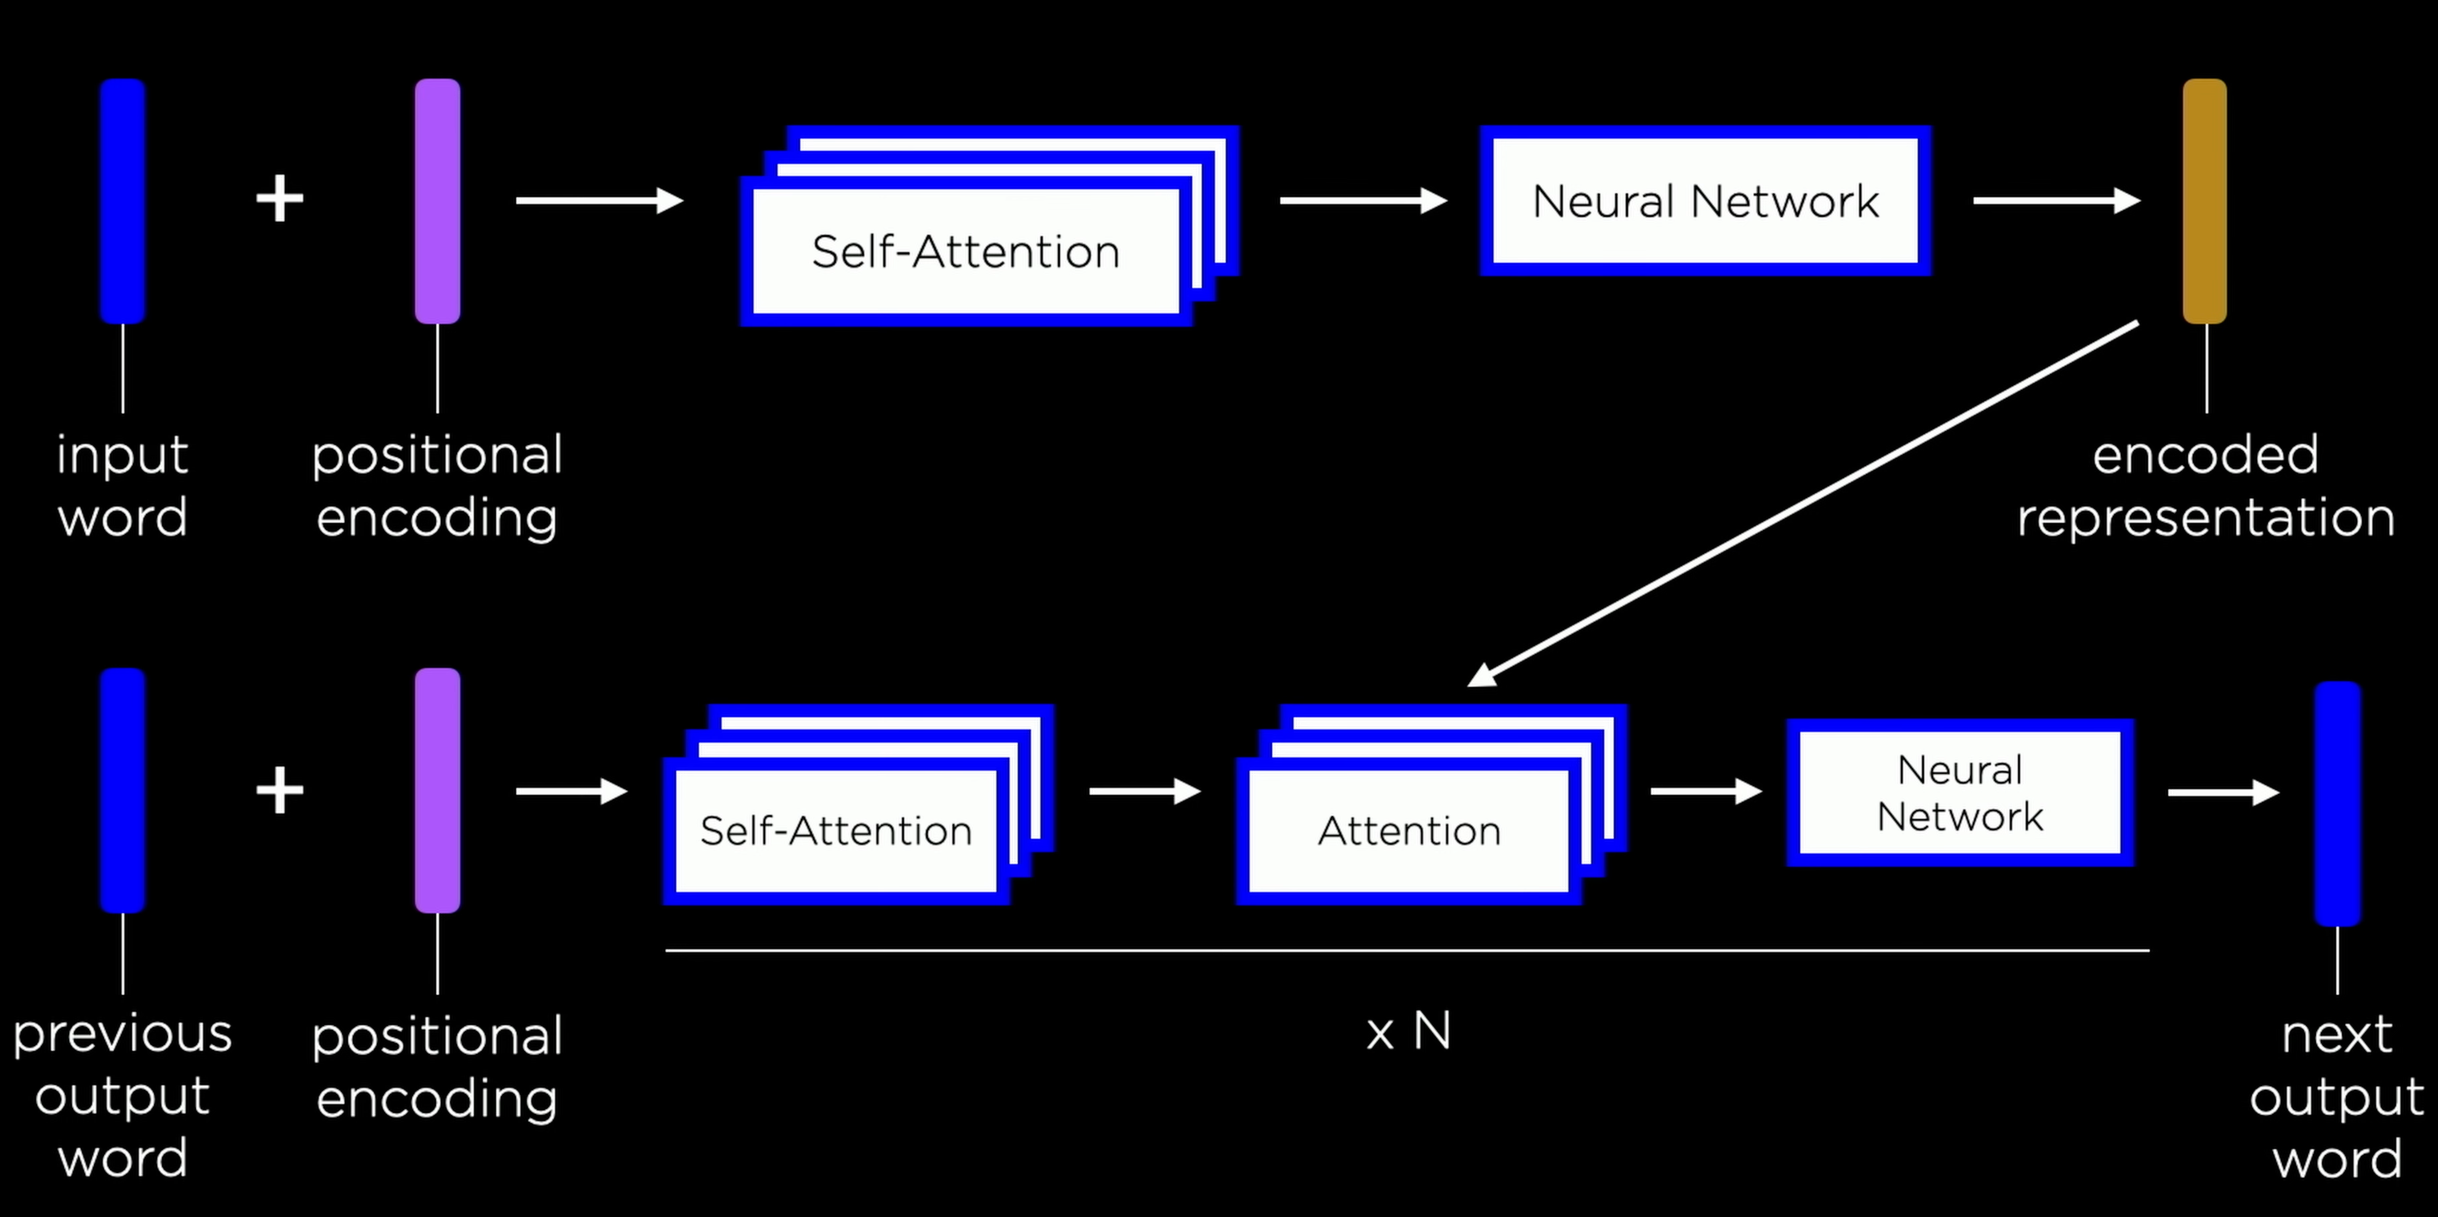
Old recurrent neural networks is sequential, not parallelized.
Decoder: for every word:
(Input word + Positional encoding)
{-> Multiple Self-attention(context) - Multi-headed attention
-> neural network} - repeating
-> encoded representation
Key idea of encoder and decoder: